With scraping data from the internet becoming more difficult, and new technologies being developed at a faster rate than ever before, I decided to build a new system (for personal use) called Prober, designed to overcome the difficulties of scraping.
Prober scrapes websites (where robots.txt allows it to) without code or the use of XPaths. Websites are constantly changing, so XPaths need changing too, even though visually nothing too drastic has changed. Prober predicts visually where certain elements are placed on a page, so you don’t need to update any XPaths. The system is trained, through visual annotation, on what an element looks like within a webpage, so it doesn’t matter if a site’s layout changes slightly. It also doesn’t interact with the DOM at all, which is what most scrapers rely on at the moment.
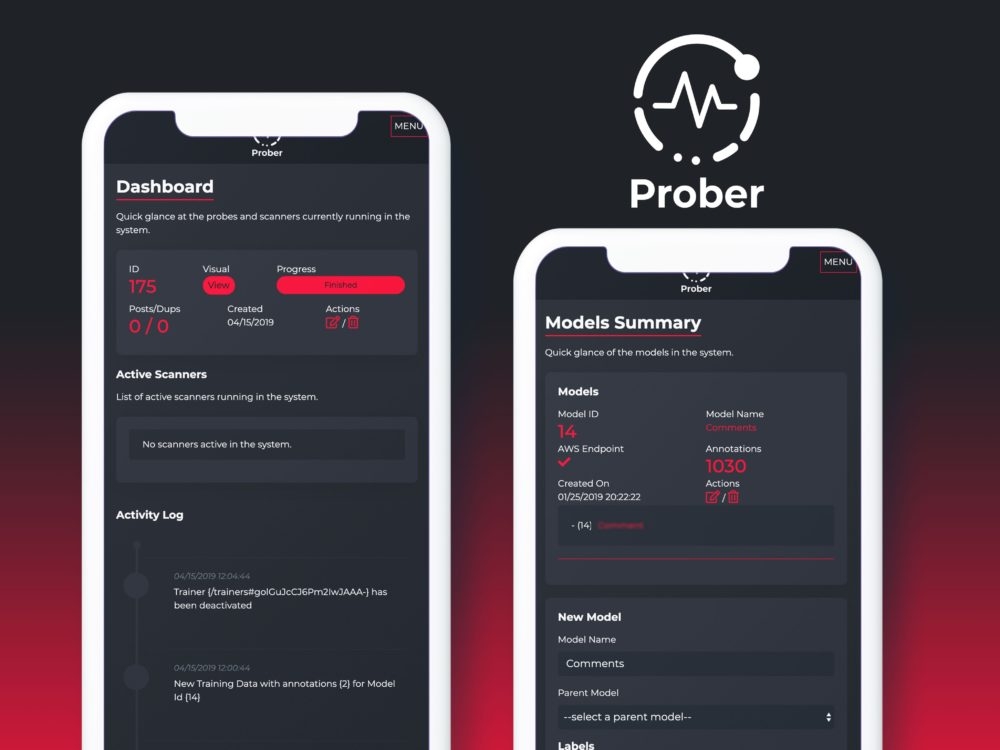
Prober is still in development, but I can see the benefits and I’m loving it!